Jul 04 2026
~ 7 min read
A discussion came up at work recently and it has been on my mind ever since.
The question was simple (and undoubtedly driven by some fear of uncertainty): Will AI ultimately make Product Managers more valuable, or software engineers? Who will still have jobs in the future?
Like many debates around AI, I think we’re asking the wrong question. The future doesn’t necessarily belong to Product Managers OR software engineers. It belongs to people who can consistently solve the right business problems using technology.
Over the past year, I’ve noticed something interesting. AI isn’t just making us more productive, it is rapidly dissolving many of the boundaries that once defined our roles.
AI Is Blurring the Lines
Historically, software organizations were built around specialization.
Product Managers understood the customer. Designers crafted the experience. Frontend engineers built the interface. Backend engineers built the services. Platform and DevOps engineers managed infrastructure. Data teams owned analytics. Security teams protected the platform, etc…
These distinctions existed for good reason. Modern software is incredibly complex, and each discipline developed deep expertise over many years. But AI is changing how we work.
Today, a Product Manager can build functional prototypes, explore databases, generate technical specifications, and validate ideas before ever involving engineering. A frontend engineer can scaffold APIs, generate database migrations, troubleshoot cloud infrastructure, and contribute to backend services. A backend engineer can confidently build polished user interfaces or improve accessibility with AI assistance. None of these people suddenly become experts outside their discipline.
But they did become dramatically more capable, and it’s clear that the distance between these roles is shrinking, fast.

The Hidden Cost of Specialization
Specialization has always made sense, but it comes with a cost we rarely talk about - communication. Every additional role introduces another handoff, which increases the overall cost of the development process.
As organizations grow, a surprising amount of engineering effort shifts away from building software and toward coordinating the people building the software.
That’s not a failure of the organization, it’s simply the cost of the existing specialization model.
What’s changing is that AI reduces the amount of expertise required to contribute meaningfully outside your primary discipline.
Instead of work moving sequentially between Product, Design, Frontend, Backend, Platform, and Data, individuals are increasingly able to move ideas forward themselves, only bringing in specialists when deep expertise is required, rather than for every incremental decision.
Ironically, this reminds me of the industry’s long pursuit of the “full-stack developer.” The idea was compelling: one engineer capable of building an entire product. But in reality, most developers naturally drifted towards one discipline or another, finding someone who could actually excel in all areas was difficult (a unicorn).
AI doesn’t change this, depth still matters, but what AI changes is the baseline.
It allows specialists to work far more effectively across adjacent disciplines, reducing unnecessary communication overhead and enabling smaller teams to deliver outcomes that once required much larger groups.
Business Understanding Becomes a Technical Skill
The best engineers I’ve worked with were never simply excellent programmers.
They understood the business.
They understood how the company made money.
They could connect technical decisions to business outcomes.
AI can accelerate implementation, but it can’t replace judgment - and the same is true for Product Managers. The strongest Product Managers increasingly understand enough about technology to reason about architecture, complexity, tradeoffs, and feasibility, not because they need to become senior engineers, but because understanding technology allows them to ask better questions and make better decisions.
Context Becomes a Competitive Advantage
As AI becomes more capable, I think one of the biggest opportunities for engineering organizations has very little to do with coding, it’s more about context.
Every company has documentation but very few have shared understanding. Most organizational knowledge lives inside people’s heads, buried in messaging conversations, old incident reports, architecture diagrams, and years of accumulated experience.
Imagine instead a living, domain-specific context repository. This idea is exactly what I introduced at Visable.
It’s not just the same old documentation, but a continuously evolving, AI agent accessible knowledge layer containing:
Business terminology and domain concepts.
Product definitions and customer workflows.
Frontend and backend service relationships.
APIs, events, and data models.
Service ownership.
Architectural decisions and their rationale.
Incident history and postmortem learnings.
Engineering standards and operational runbooks.
Combined with AI, this becomes incredibly powerful.
A new engineer can onboard in days instead of weeks.
An engineer contributing to an unfamiliar team can quickly understand the surrounding systems.
A Product Manager can answer many technical questions independently before pulling engineers into discussions.
A data analyst can understand business terminology and service relationships without relying on tribal knowledge.
Engineers spend less time answering the same contextual questions and more time solving genuinely difficult problems.
If AI becomes the interface to software development, then organizational context becomes the fuel that makes it effective. I believe in the future, accurate context will become a critical layer in our future infrastructure - “context as code”.
The Rise of the Full-Context Technologist
For years we’ve talked about T-shaped professionals - people with deep expertise in one discipline and broad knowledge across many others.
AI is pushing us one step further - the most valuable people won’t simply have breadth, they’ll have context. They’ll understand customers, business strategy, technology, operations, and AI well enough to connect ideas across traditional boundaries.
Their career might begin in Product, Engineering, Data, Design….but it won’t matter nearly as much as their ability to understand and contribute to the entire system around them.
Depth will always matter, but pairing that depth with business understanding, technical curiosity, and the ability to work across disciplines will become an increasingly valuable combination.
Looking Ahead
I don’t think software engineering is disappearing, and I don’t think Product Management is disappearing either.
Both professions will continue to evolve, but what’s changing is the distance between them.
The organizations that will thrive in the future will be those that reduce communication overhead, capture organizational context, and empower small, AI-enabled teams to move quickly.
Likewise, the professionals who thrive won’t be defined by a single job title, they’ll be defined by their ability to understand the business, leverage technology, and solve meaningful problems regardless of where those problems originate.
AI isn’t replacing our professions - it’s supercharging them.
I truly believe the people and organizations that embrace that shift early will have a significant advantage over the next five years and beyond.
share the love
The views and opinions expressed on this blog are the author's own and do not reflect those of their employer, past or present. Any content shared here is for informational purposes only and should not be taken as professional or legal advice.
The Afterburner
The conversation continues with additional thoughts, insights and commentary.In my post I mentioned a bit about what I've put together at Visable Labs to help our tech and product orgs start pushing the boundaries of the roles a bit more.
What is the "shared-context" model?
The idea is to put all of the known technical and product knowledge for a specific domain into one place, that can be queried or leveraged by AI agents more easily, and therefore other roles within your organization, say Product, Sales or Data Engineering. At Visable, we already had teams and product split by product domain (3 domains), so I split it as one "context" per domain, but it's adaptable to the shape of your org.
What does the repository contain?
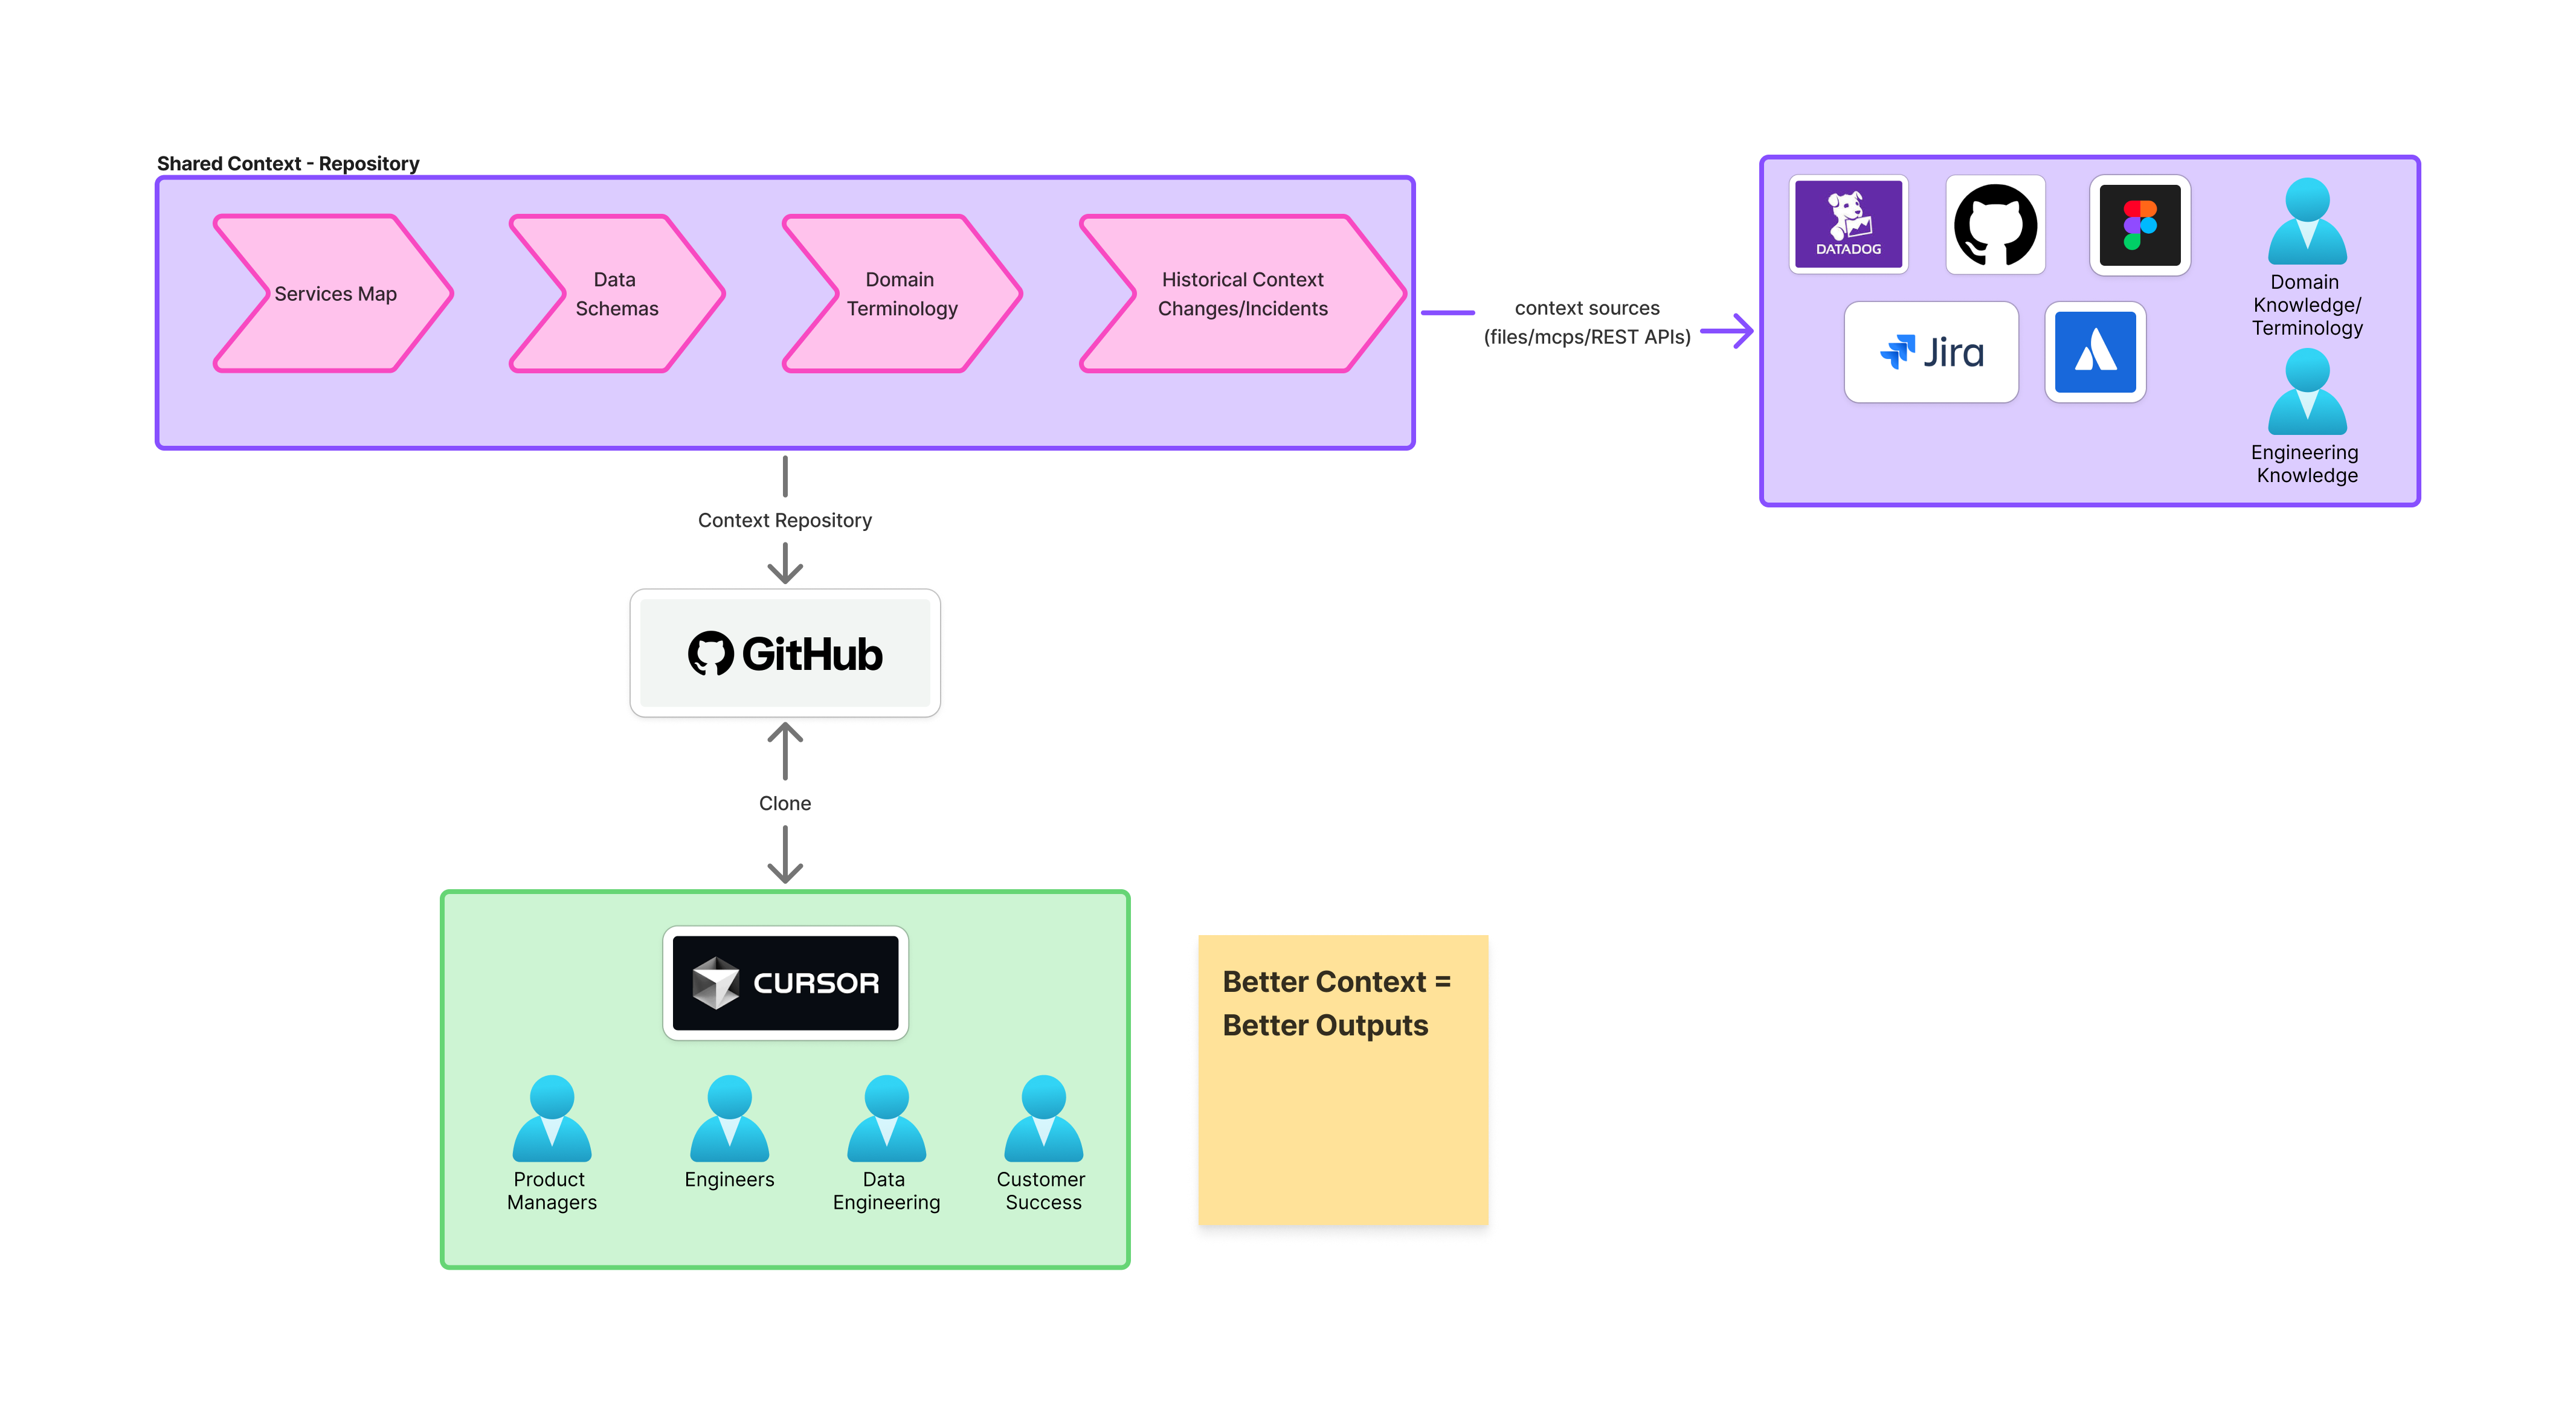
The diagram below shows how what type of information could be stored in a shared-context repository pattern, but this is also customizable based on the data sources and use cases you want agents or end-users to be able to solve for.
At the end of it, you should have a well organized knowledge pack that consolidates things like service maps, data schemas, product terminology, and even things like historical context/incidents. These could be sourced from systems like Datadog / GitHub / Jira / Wiki / Figma / tribal domain knowledge — and exposed through a context compatibility layer so everyone across multiple roles works from the same source of truth. To maintain this, you could assign an individual "maintainer" or automate refreshing critical data using something like Cursor Cloud, or your own hosted solution.
Here is a sample diagram of what it might look like:
How do I get started?
I wish I had documented the process a bit more thoroughly but in general - it would be something like this:
-
Determine who will actually use the repository and the main goals - are you going to use it for harness engineering to make your coding or outputs more accurate, or are you primarily focusing on providing a systematic way for others to get the information they need quicker and more accurately (or both)?
-
Based on the above - start small, compile key information that would be useful for AI agents day to day to get a better understanding of the domain and the problems you are trying to solve.
For example - I uploaded a digital end-to-end workflow digram out of Figma for our entire request funnel, clearly showing what happens at each stage etc... because this was important for the system to generate insights around metrics, inefficiencies, improvements and to assist with things like identifying gaps in Business Requirement document reviews (from a technical perspective), which is one of the main use cases for our context repository.
- Experiment - continue to try the repo out in different Agentic cases for your defined situations (and maybe even some you didn't expect!) Help others see the benefit of the approach and socialize it, get buy in, and ideally have everyone start contributing to it, where it makes sense.
Obviously I am skipping over some governance/responsibility questions here, and you also want to consider how much data needs to live in this versus be queried directly from other services, but if you approach it correctly it can be a useful tool that saves some costs and hopefully helps reduce some of the traditional bottlenecks around knowledge when answering important business questions or solving technical problems (query generation for example has been a huge one) outside of engineering.